Loading...
Searching...
No Matches
text.h File Reference
Text encodings and Unicode helpers. More...
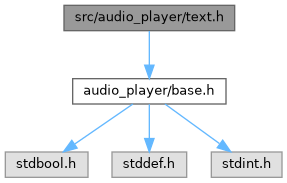
#include "audio_player/base.h"
Include dependency graph for text.h:
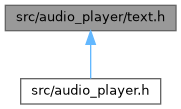
This graph shows which files directly or indirectly include this file:
Go to the source code of this file.
Enumerations | |
| enum | text_encoding_t { TEXT_ENC_LATIN1 = 0 , TEXT_ENC_UTF16_BOM , TEXT_ENC_UTF16BE , TEXT_ENC_UTF8 , TEXT_ENC_CP1251 , TEXT_ENC_AUTO_LEGACY } |
Functions | |
| size_t | text_to_utf8 (const uint8_t *in, size_t len, text_encoding_t enc, char *out, size_t out_size) |
| Convert to UTF-8. | |
| text_encoding_t | text_detect_legacy (const uint8_t *in, size_t len) |
| Heuristic for 8-bit legacy text: valid UTF-8 -> UTF8; mostly bytes 0xC0..0xFF forming Russian words -> CP1251; otherwise LATIN1. | |
| bool | text_is_valid_utf8 (const uint8_t *in, size_t len) |
| size_t | utf8_decode (const char *s, uint32_t *cp) |
| Decode one code point; returns bytes consumed (>=1) and stores cp (U+FFFD on error). | |
| size_t | utf8_encode (uint32_t cp, char out[4]) |
| size_t | utf8_strlen (const char *s) |
| code points | |
| void | utf8_truncate (char *s, size_t max_bytes) |
| Truncate to at most max_bytes without splitting a code point. | |
| void | text_trim (char *s) |
| trims ASCII whitespace in place | |
Detailed Description
Text encodings and Unicode helpers.
All strings inside the core are UTF-8.
Enumeration Type Documentation
◆ text_encoding_t
| enum text_encoding_t |
Function Documentation
◆ text_detect_legacy()
| text_encoding_t text_detect_legacy | ( | const uint8_t * | in, |
| size_t | len | ||
| ) |
Heuristic for 8-bit legacy text: valid UTF-8 -> UTF8; mostly bytes 0xC0..0xFF forming Russian words -> CP1251; otherwise LATIN1.
◆ text_is_valid_utf8()
| bool text_is_valid_utf8 | ( | const uint8_t * | in, |
| size_t | len | ||
| ) |
◆ text_to_utf8()
| size_t text_to_utf8 | ( | const uint8_t * | in, |
| size_t | len, | ||
| text_encoding_t | enc, | ||
| char * | out, | ||
| size_t | out_size | ||
| ) |
Convert to UTF-8.
Stops at NUL or len. Always terminates out. Returns bytes written (without terminator). Invalid sequences become U+FFFD.
◆ text_trim()
| void text_trim | ( | char * | s | ) |
trims ASCII whitespace in place
◆ utf8_decode()
| size_t utf8_decode | ( | const char * | s, |
| uint32_t * | cp | ||
| ) |
Decode one code point; returns bytes consumed (>=1) and stores cp (U+FFFD on error).
◆ utf8_encode()
| size_t utf8_encode | ( | uint32_t | cp, |
| char | out[4] | ||
| ) |
◆ utf8_strlen()
| size_t utf8_strlen | ( | const char * | s | ) |
code points
◆ utf8_truncate()
| void utf8_truncate | ( | char * | s, |
| size_t | max_bytes | ||
| ) |
Truncate to at most max_bytes without splitting a code point.